COLT 2025
Taking a Big Step: Large Learning Rates in Denoising Score Matching Prevent Memorization
Large learning rates implicitly regularize denoising score matching and prevent memorization.
In brief
- Problem. The exact minimizer of denoising score matching memorizes the training data, yet trained models memorize only mildly.
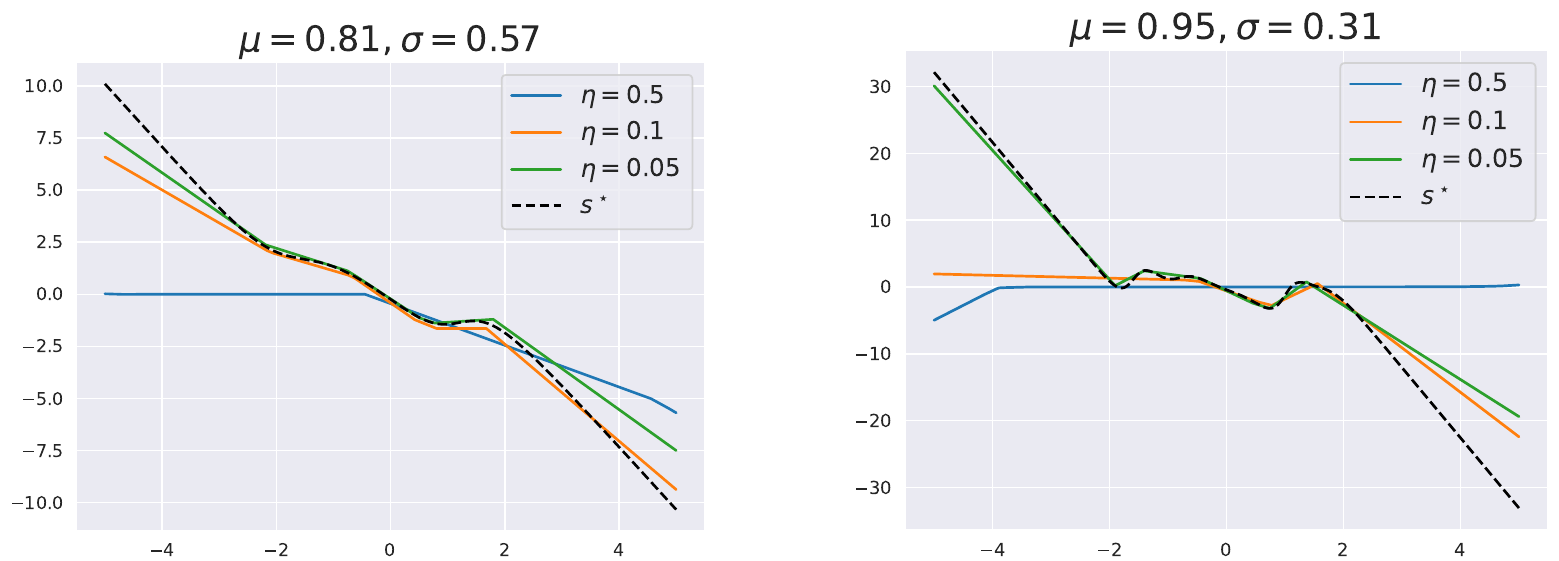
- Approach. Analyze gradient descent with large steps, which can only converge to minima whose sharpness is bounded by the inverse learning rate.
- Result. The memorizing solution is too sharp to be reached; large learning rates prevent memorization.
Abstract
Denoising score matching plays a pivotal role in the performance of diffusion-based generative models. However, the empirical optimal score–the exact solution to the denoising score matching–leads to memorization, where generated samples replicate the training data. Yet, in practice, only a moderate degree of memorization is observed, even without explicit regularization. In this paper, we investigate this phenomenon by uncovering an implicit regularization mechanism driven by large learning rates. Specifically, we show that in the small-noise regime, the empirical optimal score exhibits high irregularity. We then prove that, when trained by stochastic gradient descent with a large enough learning rate, neural networks cannot stably converge to a local minimum with arbitrarily small excess risk. Consequently, the learned score cannot be arbitrarily close to the empirical optimal score, thereby mitigating memorization. To make the analysis tractable, we consider one-dimensional data and two-layer neural networks. Experiments validate the crucial role of the learning rate in preventing memorization, even beyond the one-dimensional setting
Cite
Yu-Han Wu, Pierre Marion, Gérard Biau and Claire Boyer (2025). Taking a Big Step: Large Learning Rates in Denoising Score Matching Prevent Memorization. In Proceedings of the Thirty Eighth Conference on Learning Theory (COLT), PMLR 291:5718–5756.
@inproceedings{wu2025taking,
  title={Taking a Big Step: Large Learning Rates in Denoising Score Matching Prevent Memorization},
  author={Wu, Yu-Han and Marion, Pierre and Biau, G{\'e}rard and Boyer, Claire},
  booktitle={Proceedings of the Thirty Eighth Conference on Learning Theory ({COLT})},
  series={Proceedings of Machine Learning Research},
  volume={291},
  pages={5718--5756},
  year={2025}
}