ICLR 2024 Spotlight
Implicit regularization of deep residual networks towards neural ODEs
Residual networks initialized as neural ODE discretizations stay so throughout gradient-flow training.
In brief
- Problem. The link between residual networks and their continuous-depth analogue, neural ODEs, lacked a mathematical foundation.
- Approach. Study gradient flow on deep residual networks initialized as discretizations of a neural ODE.
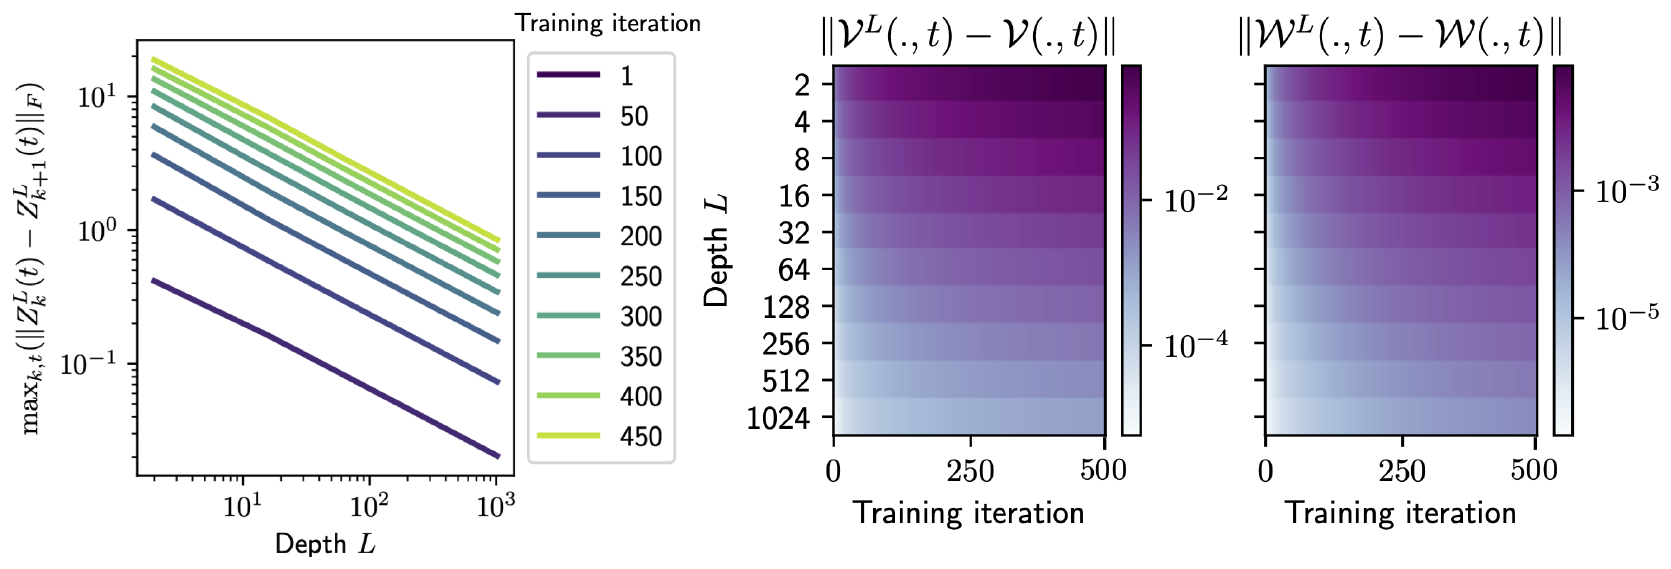
- Result. The discretization structure is preserved throughout training, for finite time and, under a Polyak–Łojasiewicz condition, as time goes to infinity, with convergence to a global minimum.
Abstract
Residual neural networks are state-of-the-art deep learning models. Their continuous-depth analog, neural ordinary differential equations (ODEs), are also widely used. Despite their success, the link between the discrete and continuous models still lacks a solid mathematical foundation. In this article, we take a step in this direction by establishing an implicit regularization of deep residual networks towards neural ODEs, for nonlinear networks trained with gradient flow. We prove that if the network is initialized as a discretization of a neural ODE, then such a discretization holds throughout training. Our results are valid for a finite training time, and also as the training time tends to infinity provided that the network satisfies a Polyak-Łojasiewicz condition. Importantly, this condition holds for a family of residual networks where the residuals are two-layer perceptrons with an overparameterization in width that is only linear, and implies the convergence of gradient flow to a global minimum. Numerical experiments illustrate our results.
Cite
Pierre Marion, Yu-Han Wu, Michael E. Sander and Gérard Biau (2024). Implicit regularization of deep residual networks towards neural ODEs. In The Twelfth International Conference on Learning Representations (ICLR).
@inproceedings{marion2024implicit,
  title={Implicit regularization of deep residual networks towards neural {ODEs}},
  author={Marion, Pierre and Wu, Yu-Han and Sander, Michael E. and Biau, G{\'e}rard},
  booktitle={The Twelfth International Conference on Learning Representations ({ICLR})},
  year={2024}
}